Bixoto Research · Decision Index 0.3
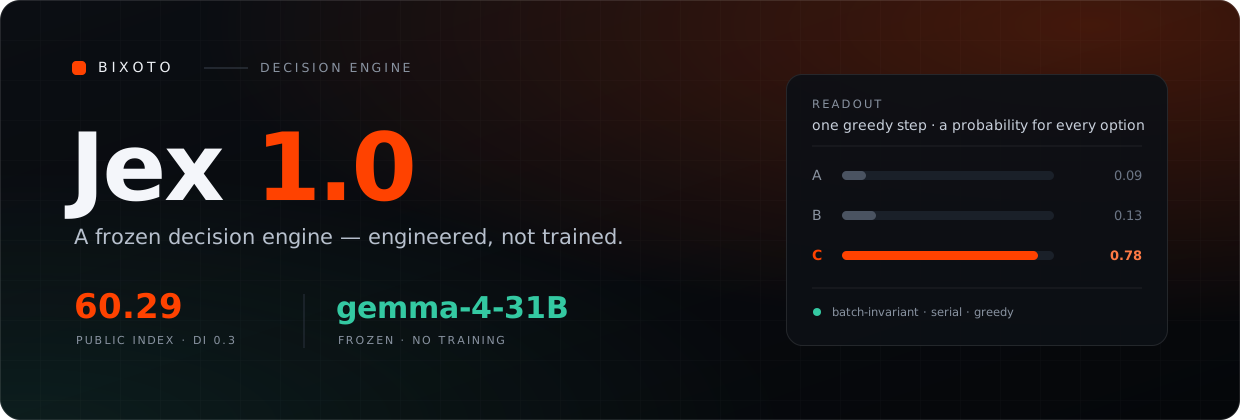
Jex 1.0
The strongest frozen decision engine on Decision Index 0.3.
A stock gemma-4-31B checkpoint driven to a 60.29 public index by a deterministic inference engine. No head, no LoRA, no fine-tuning — every point over the
next-best frozen entry comes from the engine around the model.
Self-reported public index, official kit scorer, complete run, bit-exact re-score. Full score pending — private legs run by maintainers.
Why it's different
Engineered, not trained.
The base checkpoint is untouched (rev 842da379…, bf16). The
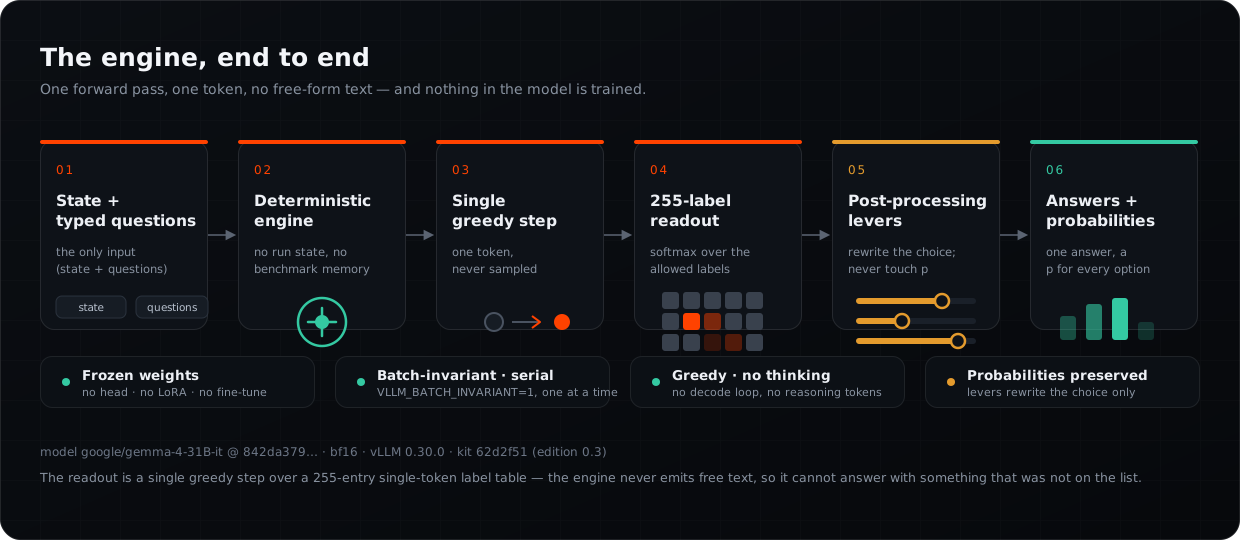
readout is a single greedy step over a 255-entry single-token label table. Nothing about the
model's forward pass changes.
The cleanest head-to-head on the board.
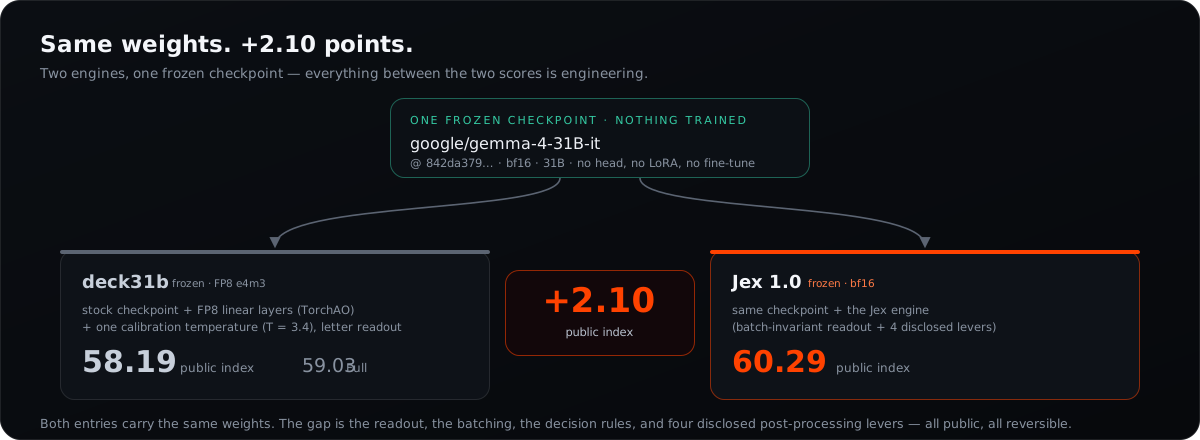
deck31b runs the same gemma-4-31B-it checkpoint with FP8 and
one temperature and lands at 58.19 public. Jex 1.0
lands at 60.29. Everything between the two entries is
engine work — and it is all public.
Determinism you can verify at home.
Batch-invariant and serial — a pure function of (state, questions) plus frozen constants. The packaged
results file re-scores bit-exact 60.29 under two
independent scorers.
Every number has a receipt.
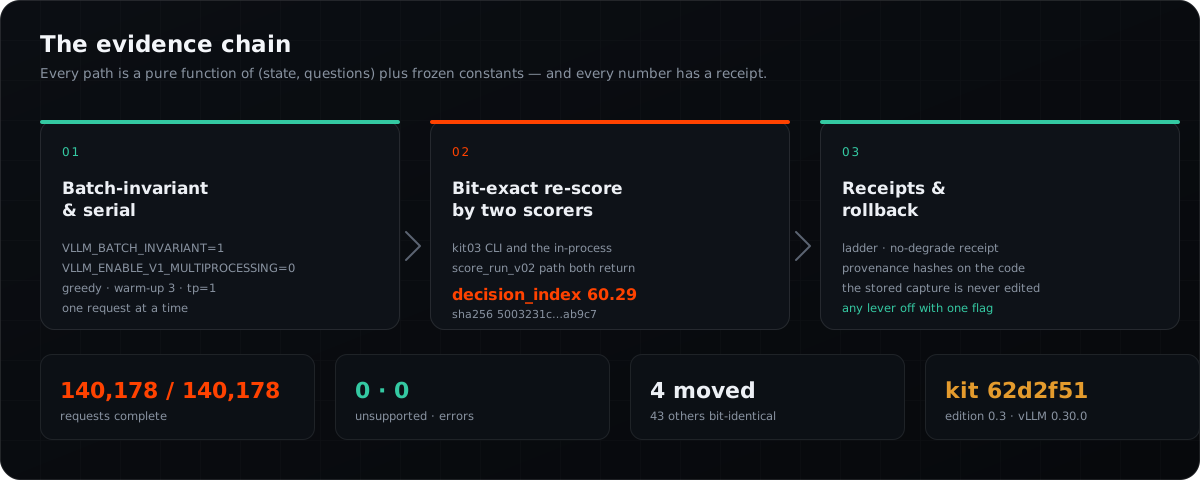
A documented ladder with leave-one-out checks, a no-degrade receipt, provenance hashes on the lever code, one-flag rollback, and honest disclosure of the two projection classes.
Same weights. +2.10 points.
The board has exactly two serious frozen entries, and they run the same checkpoint. deck31b runs google/gemma-4-31B-it frozen; Jex 1.0 runs the same frozen
checkpoint through a different engine. 58.19 vs 60.29 — a +2.10 difference that is entirely engineering: the readout, the batching, the decision rules, and four
disclosed post-processing levers.
The result
The public index is the chance-corrected score over the 37-benchmark public panel (5 areas). It is not the board's Full score, which adds 50% private same-skills tests and 30% private new-domain tasks run by the maintainers. No Full-score or rank claim is made.
| metric | value |
|---|---|
| public index (Decision Index 0.3) | 60.29 |
| balanced raw | 69.88 |
| breadth skill | 59.25 |
| requests | 140,178 / 140,178 ok |
| unsupported · error | 0 · 0 |
| complete | true |
| coverage | 1.0 (no reasoning) |
The ladder
Every step is cumulative and receipted on the same 140,178 requests. The four levers add +0.81 together.
| step | stack | public index |
|---|---|---|
| base | frozen capture, no levers | 59.48 |
| + fold | cat62 fold (D, τ = −13.63) | 59.96 |
| + c05best | cat59 isotonic · shrink λ = 0.75, nf = 10 | 60.09 |
| + R42 | cat42 Entailment (τ = −8) | 60.21 |
| + R20 | cat20 option_0 (τ = +15) | 60.29 |
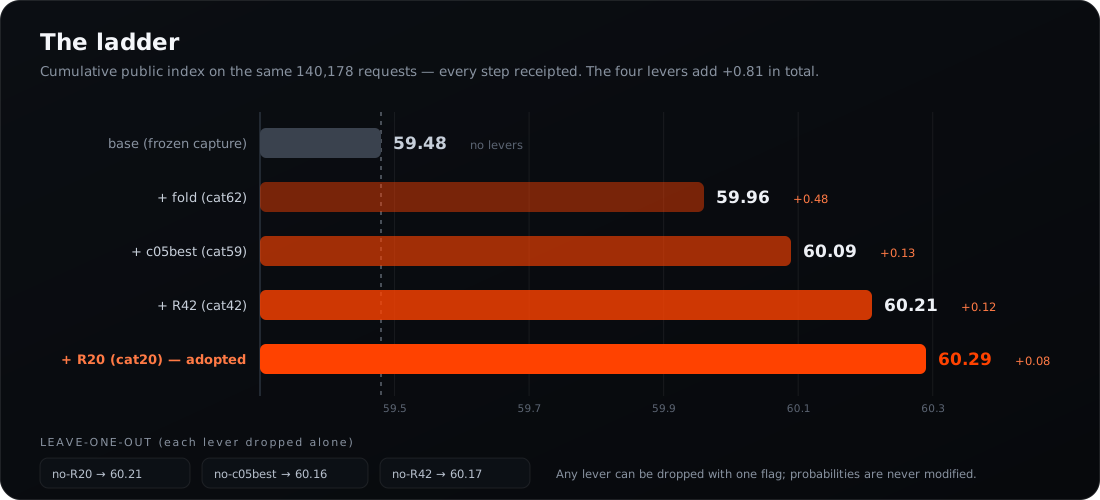
Leave-one-out checks (each lever dropped in isolation): no-R20 → 60.21 · no-c05best → 60.16 · no-R42 → 60.17. Exactly four catalogs move (62, 59, 42, 20); every other catalog is bit-identical — the 43/43 no-degrade receipt.
The four levers
| lever | catalog | rule | provenance |
|---|---|---|---|
| fold | 62 When2Call | emit D if logit(p_work[D]) ≥ −13.63 | positional construction-reuse → public-suite projection |
| c05best | 59 RAGTruth (noul) | isotonic · shrink λ = 0.75, nf = 10 (OOF) | fitted on the public OOF panel |
| R42 | 42 NLI4CT | emit Entailment if logit ≥ −8 | threshold fitted on the public OOF panel |
| R20 | 20 BPoMP | emit option_0 if logit ≥ +15 | positional construction-reuse → public-suite projection |
Probabilities are never modified: only the emitted choice (recovered
to the pre-TBO rule space) and the cat59 noul field are overwritten.
The stored capture is never edited.
Two lever classes are disclosed as projections: fold (cat62) and R20 (cat20) are public-suite positional projections; c05best (cat59) and R42 (cat42) are public-OOF fits.
Where Jex sits on the public index
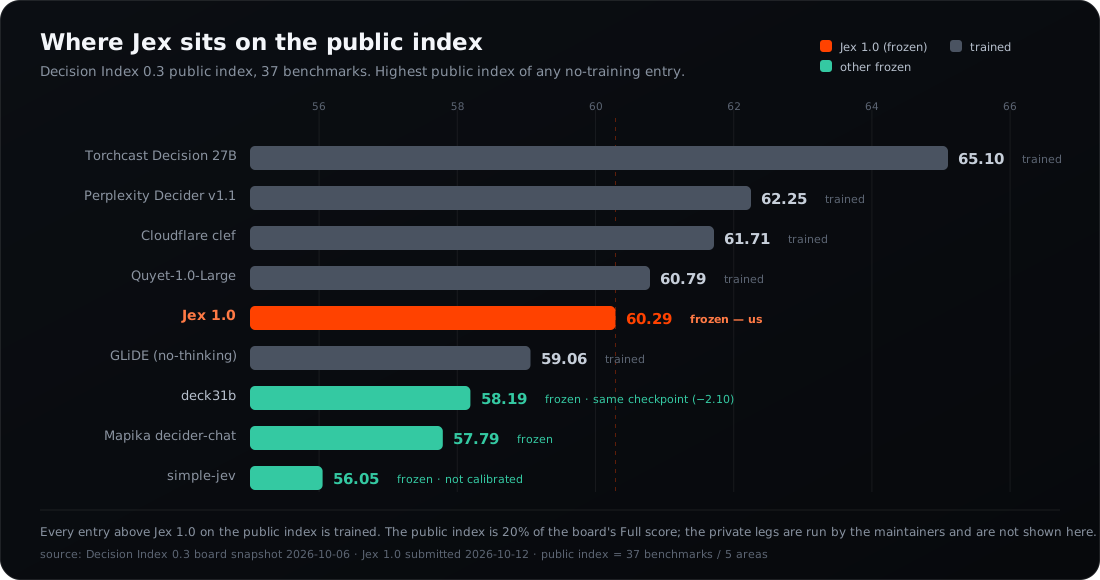
Every entry above Jex 1.0 on the public index is trained. Among no-training entries, the next best is
deck31b (58.19, same checkpoint) — +2.10; then Mapika's frozen decider-chat (57.79) and simple-jev (56.05).
| entry | training | public index | Full | median ms |
|---|---|---|---|---|
| Torchcast Decision 27B | LoRA | 65.10 | 59.91 | 99.9 |
| Perplexity Decider v1.1 (27B) | full fine-tune | 62.25 | 62.75 | 104.1 |
| Cloudflare clef | post-trained | 61.71 | 53.08 | 102.1 |
| Quyet-1.0-Large | LoRA | 60.79 | 58.71 | 105.4 |
| Jex 1.0 | none — frozen | 60.29 | pending | 116.4 |
| GLiDE (Fastino, no-thinking) | full fine-tune | 59.06 | 60.21 | 98.4 |
| deck31b | none — frozen | 58.19 | 59.03 | 218.5 |
| Mapika decider-chat | none — frozen | 57.79 | 57.62 | 108.5 |
| simple-jev | none — frozen | 56.05 | 51.79 | 373.0 |
Board snapshot 2026-10-06; Jex 1.0 submitted 2026-10-12. "Full" and peer public-index figures are the board's own numbers, not ours.
Latency, on the board's own protocol
Measured on one RTX PRO 6000 96 GB, single process, one request at a time — the board's admission protocol (n = 750 timed rows, serial, batch-invariant).
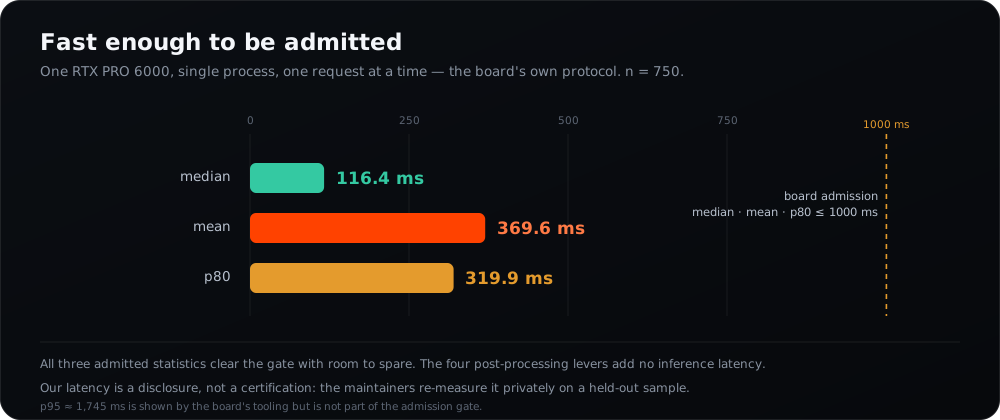
The four post-processing levers add no inference latency. This is a disclosure, not a certification: the maintainers re-measure latency privately on a held-out sample. p95 (≈ 1,745 ms) is displayed by the board's tooling but is not part of the admission gate.
Reproducibility
The packaged combined file re-scores bit-exact 60.29 under two
independent scorers: the kit03 CLI and the in-process score_run_v02 path. Every path is a pure function of (state, questions) plus frozen
constants — batch-invariant (VLLM_BATCH_INVARIANT=1) and serial
(VLLM_ENABLE_V1_MULTIPROCESSING=0), greedy, determinism warm-up 3, TRITON_ATTN, FULL_DECODE_ONLY,
tp = 1.
| pin | value |
|---|---|
| base model | google/gemma-4-31B-it @ 842da3794eaa0b77d5f08bae87a17459d91ff475 (bf16) |
| kit / edition | 62d2f51de34a2de64906345b6bc3e98e27ff55c7 (edition 0.3) |
| runtime | vLLM 0.30.0, transformers 5.14.1 |
| results file sha256 | 5003231c9757d430ff9439c17a0e20f166b8d3dacef1dcde66e49056708ab9c7 |
| hardware | 1 × NVIDIA RTX PRO 6000 96 GB (Blackwell, sm_120) |
- Rollback: drop any single lever by re-running
levers/run_variants.pywith that flag set toFalse. Dropping the whole stack returns to the base 59.48. - The reproduction inputs — the frozen base capture, the fitted
table.pkl, and the cat62 folded file — ship with the results dataset underruns/jex-1.0/inputs/. The evaluation kit and suite are a third party's; fetch them from the officialapolinario/decision-indexcheckout.
One forward pass. One token. No free-form text.
Jex 1.0 is a decision engine, not a language model. Give it a state and a set of typed questions and it returns one answer per question with a probability for every allowed option — with no output parsing, and nothing that was not on the list.
- 1. Decision rules — signature-scoped rules (iSarcasm / ACOS / FinEntity).
- 2. K = 2 option-position prior — a decision transform on position 0 (the first presented option).
- 3. TBO — temperature by options: max(0.05, 10.124 − 1.633 · ln n).
- 4. Forced-choice fallback — every option carries a probability; no option is filtered, nothing is truncated.
The dual-config router runs two batch-invariant workers: ≤ 8190 tokens on an 8192 worker, longer on a 24576 worker. Prompts above 24576 tokens are declared unsupported, counted as wrong, and never truncated (0 on the public suite).
Disclosures & limitations
- Public ≠ Full. 60.29 is a public index. The board's Full score adds 50% private same-skills and 30% private new-domains run by the maintainers. No Full-score or rank claim is made.
- Positional construction-reuse (fold/cat62, R20/cat20). Both key on
the literal option position/identity the benchmark construction assigns to the gold answer
(
D; first option). Genuine and reproducible on the public suite (cat62 skill 0.6904 → 0.8324; cat20 0.8613 → 0.9094), but unverifiable on a private run whose construction is not a twin. Disclosed as public-suite projections, not claims about unseen construction. - Public-OOF fits (c05best/cat59, R42/cat42). Selected on the public out-of-fold panel; a private panel may regress toward the base rate. Neither writes probabilities — both change only the discrete decision.
- Latency is a disclosure, not a certification, measured by us on one RTX PRO 6000; the maintainers re-measure privately.
- Private-leg transport is not ours to control. A small (±0.5) drift on the private legs is possible.
- No #1 claim. The trained leader sits well above the frozen ceiling; raising it needs training, which is out of scope by design and disclosed.
- All work is AI-assisted.
- Unofficial entry. Jex 1.0 is an independent, unofficial run on Decision Index 0.3, submitted by Bixoto; no affiliation with or endorsement by the benchmark's maintainers is implied. Gemma is a trademark of Google LLC; the base weights are under the Gemma terms of use. The evaluation suite is not redistributed.
- Not for high-stakes decisions.
Explore the work
GitHub — Bixoto/jex
The engine, the harness, the levers, and the full receipts.
HF — model card
Jex 1.0 on the Hub (card-only; no weights).
HF — results dataset
The complete run, score files, and reproduction inputs
(runs/jex-1.0/).
Submission PR #153
The entry on the Decision Index board.
Decision Index kit
The official reproduction kit this run was scored with.
Base model
google/gemma-4-31B-it on the Hub.
Built at Bixoto for production use. Now open. · All AI-assisted.
Self-reported public index, official kit scorer, complete run, bit-exact re-score. Full score pending — private legs run by maintainers.